Case study · Kaneff Group
Moving seven terabytes was the easy part.
Kaneff Group held more than 7 TB of documents across on-premise servers — no naming standards, large volumes of duplicates, and thousands of scanned drawings and PDFs that no search could reach. Any supplier could have copied it all to the cloud. We read it first, then decided what deserved to move.
- Client
- Kaneff Group
- Sector
- Real estate & property management
- Services
- Cloud & Transformation · AI Engineering
- Volume
- 7 TB+ of documents
- Outcome
- Delivered on time, nothing lost
Twenty years of documents, and no map.
Kaneff Group runs real estate and property management. Leases, drawings, contracts, inspections, correspondence — the business runs on paperwork, and two decades of it had accumulated across on-premise servers, department by department, with nobody responsible for the whole.
There were no naming standards, so the same lease might be filed four different ways. Duplicates had multiplied to the point where nobody could say which version was authoritative. Thousands of scanned drawings and PDFs held no readable text at all, so no search would ever find them — people rebuilt work that already existed because finding it took longer.
Behind that sat two quieter problems. Storage costs were rising every year with no plan to change it. And with no retention rules and no record of who changed what, the organisation couldn't have evidenced its position if anyone had asked.
The obvious project was to copy it all into the cloud. That would have relocated the problem, added a monthly bill, and spent the only budget anyone was ever going to get for fixing it.
Three things made this more than a file move.
Each one would have derailed the programme if it had been treated as a detail to sort out later.
There was no inventory. You can't plan a migration against an unknown estate, and you certainly can't promise nothing will be lost. Everything downstream depended on understanding the 7 TB first — which is work most migrations skip.
Scanned drawings, signed contracts and photographed documents are images as far as a computer is concerned. Moving them to a modern platform changes nothing — they arrive just as invisible as they left.
Property management runs on those documents every working day. There was no window in which the estate could be frozen, so people had to keep working while it moved beneath them.
A classification engine made for Kaneff's documents.
Not an off-the-shelf migration tool. We built software that understood what a Kaneff lease, drawing or inspection report looks like — because generic classification on twenty years of specific paperwork produces confident nonsense.
Text recognition ran across every scanned file, turning images of documents back into text a search can reach. That single step is why a drawing filed in 2009 can now be found by typing the property name.
- Scanned PDFs, drawings and photographed documents processed
- Full-text search across the entire estate, not just recent files
- Low-confidence results routed to a person rather than guessed
The engine classified each file by type and by owning department, then applied consistent naming at a scale no manual process could reach. SharePoint sites were designed around how Kaneff's departments actually work, not around a generic template.
- Department-specific sites, structured to match real workflows
- Consistent naming applied automatically across the whole estate
- Labels and properties applied as files landed, not added afterwards
- Access limited to the departments that should hold each document
Retention rules and archival workflows were applied as part of the move, so the platform stays clean without depending on anyone remembering. An audit trail is generated as a by-product of normal use rather than assembled when someone asks.
- Retention applied automatically by document type
- Archival workflows that run without manual intervention
- A record of what exists, who changed it and when
- Storage that scales without buying hardware
We deleted before we moved.
Almost every migration copies everything first and promises to tidy up afterwards. It never happens — once the business is running on the new platform, nobody gets budget to go back and sort out files that appear to be working fine. So you pay to store two decades of duplicates, forever.
We found and removed the duplicates before anything moved. That is harder. It requires understanding the estate first, agreeing what counts as authoritative, and taking responsibility for a decision to delete. It's also the entire reason Kaneff's storage went down by a fifth after a migration, rather than up.
Duplicates were identified by reading the documents, not by comparing file names — the same lease saved four ways has four different names.
Every removal appeared in the validation report for that phase, with the retained version named. Kaneff signed off before the next phase began.
The confusion wasn't only cost. When four versions of a contract exist, someone eventually acts on the wrong one. That risk left with the duplicates.
Around a fifth of the storage bill, permanently removed — on an estate that had been growing every year with no plan to stop.
The same documents. A different organisation.
- No naming standards or structure across departments
- Duplicates everywhere, with no authoritative version
- Scanned drawings and contracts invisible to search
- No retention rules and no record of changes
- On-premise storage costs climbing every year
- Documents siloed on servers, hard to reach remotely
- One filing structure, aligned to how each department works
- Duplicates removed before migration, one version retained
- Every document searchable, scanned files included
- Retention applied automatically, audit record generated
- A fifth less storage, and no hardware ceiling ahead
- Available wherever people work, with access controlled
Department by department, proven each time.
No single cutover, no batch move run overnight and hoped for. Each phase was verified before the next one started, and the old environment stayed available throughout.
We analysed real files from multiple departments to map what document types existed, how they were named, what had to be kept and for how long, and where the compliance exposure sat across the full estate.
A target SharePoint structure designed around department workflows, and a classification engine built specifically for Kaneff's document types rather than adapted from a generic tool.
Files read, classified, renamed, deduplicated and given their retention rule automatically — with a validation report after each department showing exactly what moved, what was removed and what needed a decision.
Retention and archival workflows switched on, audit record established, and the team trained to run it themselves. Documentation written as we went rather than assembled at the end.
The best outcome was that they didn't need us afterwards.
Kaneff runs the platform independently. The rules apply themselves, the structure holds because it matches how the departments actually work, and adding a new document type doesn't require a phone call to us.
We'd rather say that plainly than imply an ongoing dependency. A migration that leaves the client needing the supplier to keep it tidy hasn't finished — it has just moved the problem into a support contract.
Conventional platform, custom intelligence.
The destination was deliberately mainstream — Kaneff's team already knew Microsoft, and a document platform has to be maintainable for a decade. The custom work went where it earned its place: understanding the documents.
- SharePoint Online
- Microsoft 365
- Power Automate
- Secure cloud execution
- Custom classification engine
- Text recognition for scans
- Duplicate detection
- Automated naming
- Retention rules by type
- Archival workflows
- Access control
- Audit reporting
- Per-phase validation reports
- Parallel running
- Sign-off between phases
- Handover documentation
Related case studies.
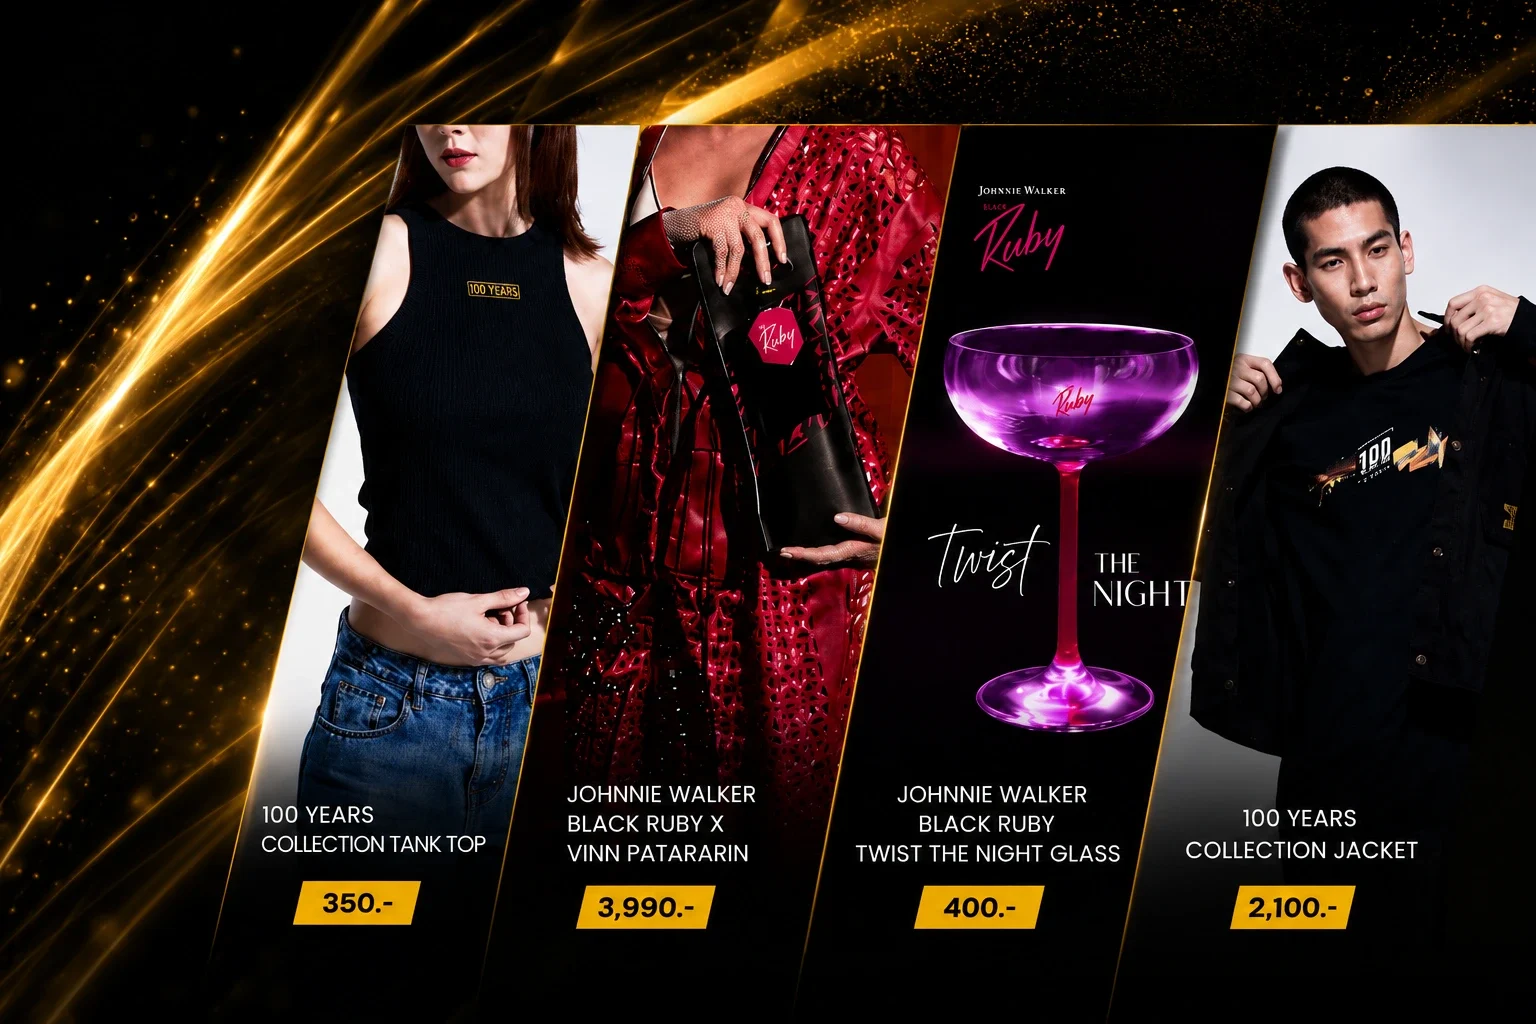
Johnnie Walker Style is a Thai-language merchandise store trading in baht. We moved it off a custom PHP build onto Shopify — same products, same customers, same URLs where it mattered, a different engine underneath. Since then we've supported and extended it. A migration that generates a story for the customer has usually gone wrong.
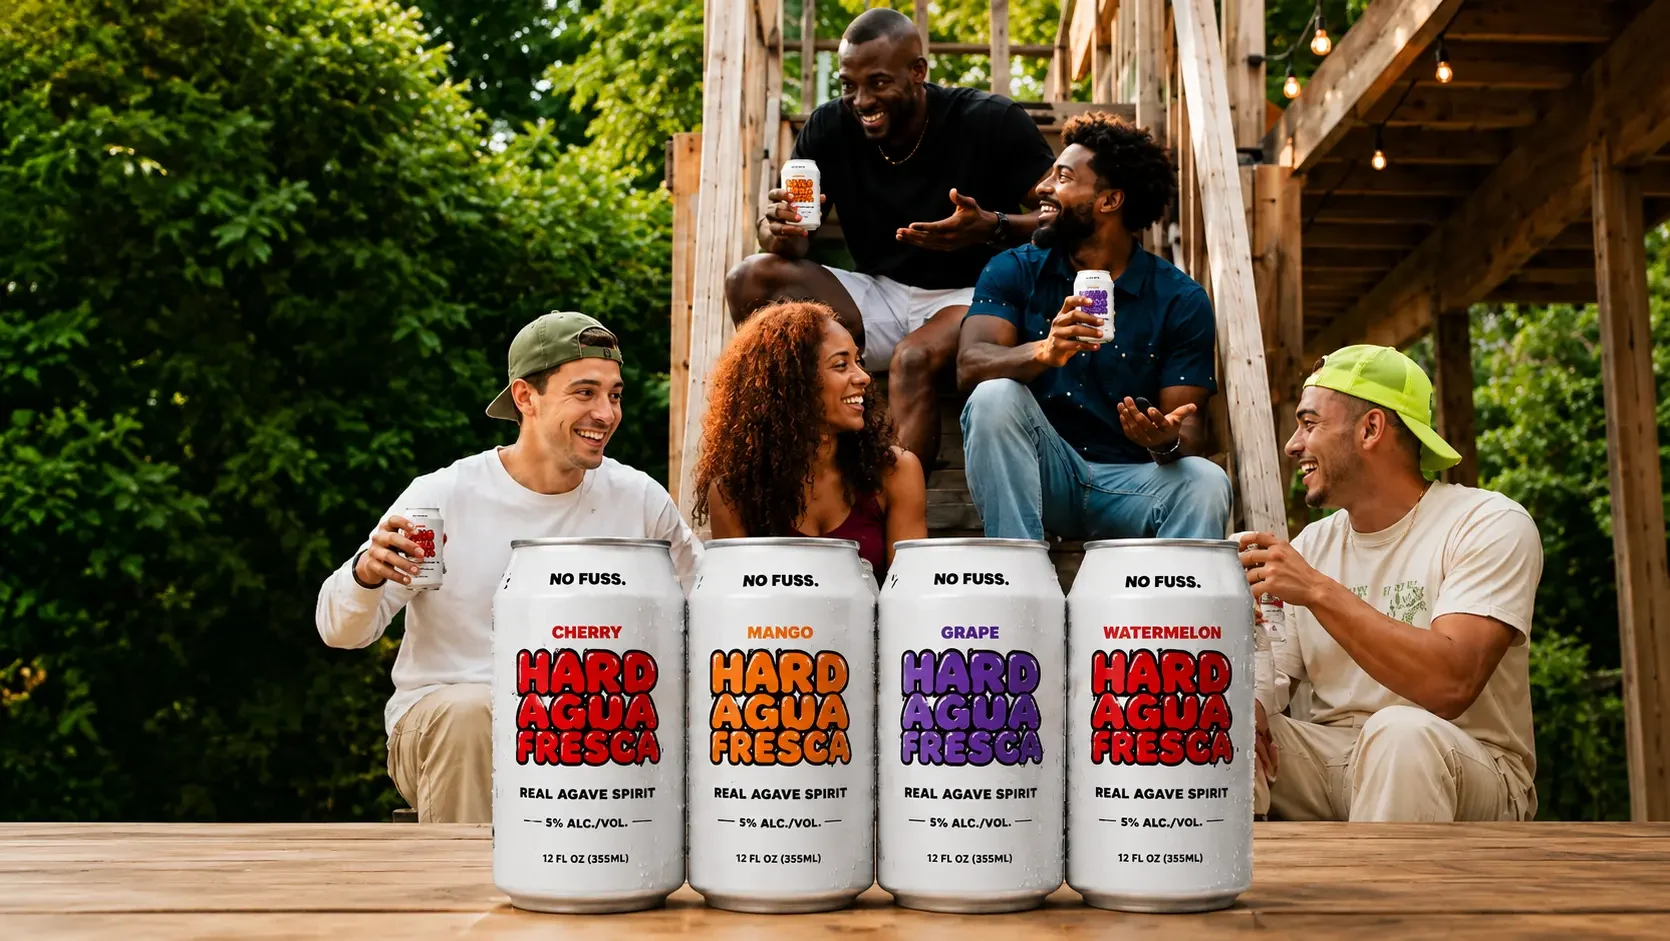
Stoop Dayz is hard soda for people with no plans — “all flavor, no fuss”, built on the idea that the best moments were never scheduled. Almost every default move in web marketing works against that. Pop-ups, countdowns, urgency, sign-up interruptions. We designed the site without any of them, and made it earn attention rather than demand it.